Percona Operator for MySQL 1.3.0 is out. This release moves three things forward for teams running MySQL on Kubernetes: the operator now tunes MySQL for you based on the pod resources, async clusters can fail over without losing data in flight, and point-in-time recovery works on clusters where binary logs are encrypted at rest.
The headline features in this post are automatic MySQL configuration tuning, zero data loss failover for asynchronous clusters, and encrypted binary logs for point-in-time recovery. Each of them removes a step that teams were doing by hand, or a case they had to accept as a known gap.
As with every operator release, most of what shipped came from what the community asked for on forums.percona.com and in JIRA. The operator is open source and runs on any CNCF-conformant Kubernetes.
In this post, you’ll learn about:
1.3.0Two defaults changed in 1.3.0. Review both before upgrading.
The operator now runs with leader election enabled out of the box. In every realistic deployment this is what you want. If you have a single-replica controller and want the old behavior for a specific reason (local development, debugging), set the PSO_LEADER_ELECTION_ENABLED environment variable on the operator Deployment to false.
This is the one that will trip an upgrade. In 1.3.0, async clusters must have backups enabled, because the zero data loss failover feature (below) relies on reading binary logs from the failed primary. If backups are not configured on an async cluster, the operator refuses to reconcile.
You have two options:
|
1 2 3 |
spec: unsafeFlags: asyncFailoverWithPossibleDataLoss: true |
This restores the pre-1.3.0 behavior: fast failover, but transactions committed on the old primary that had not yet reached the chosen replica are lost.
Group Replication clusters are unaffected by this change.
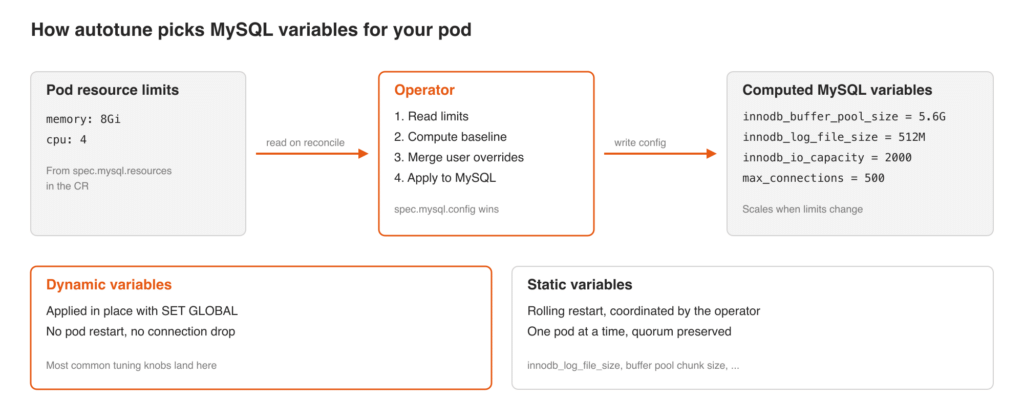
Tuning MySQL by hand for a given pod shape is work most teams do once and then forget. When the pod resource limits change, the hand-tuned values rarely follow. 1.3.0 adds a first-class autoConfig block to the CR so the operator computes the MySQL configuration from the pod’s CPU and memory, and the workload shape you declare.
The relevant fields live under spec.mysql.autoConfig. enabled turns the feature on, loadType tells the operator the workload shape, and version tells it which MySQL version to tune for. The accepted loadType values are mostlyReads, someWrites, equalReadsWrites, and heavyWrites. The version string follows the X.Y.Z MySQL version format.
The CRD enforces that mysql.resources sets both CPU and memory when autoConfig.enabled is true. Without those limits, the operator has no basis for its calculation.
Where a MySQL variable allows it, the operator applies configuration changes with SET GLOBAL instead of a restart. Static variables still require a restart, which the operator rolls through pods one at a time.
The following block comes from the sample CR in the operator repository:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 |
apiVersion: ps.percona.com/v1 kind: PerconaServerMySQL metadata: name: cluster1 spec: mysql: size: 3 resources: limits: memory: 8Gi cpu: 4 autoConfig: enabled: true loadType: someWrites version: 8.4.0 |
With that block, the operator sizes the buffer pool and friends from the 8 GiB / 4 CPU limits, biases the configuration toward a mixed workload with some writes, and tunes for MySQL 8.4.0. Change the limits or the load type and the operator recomputes.
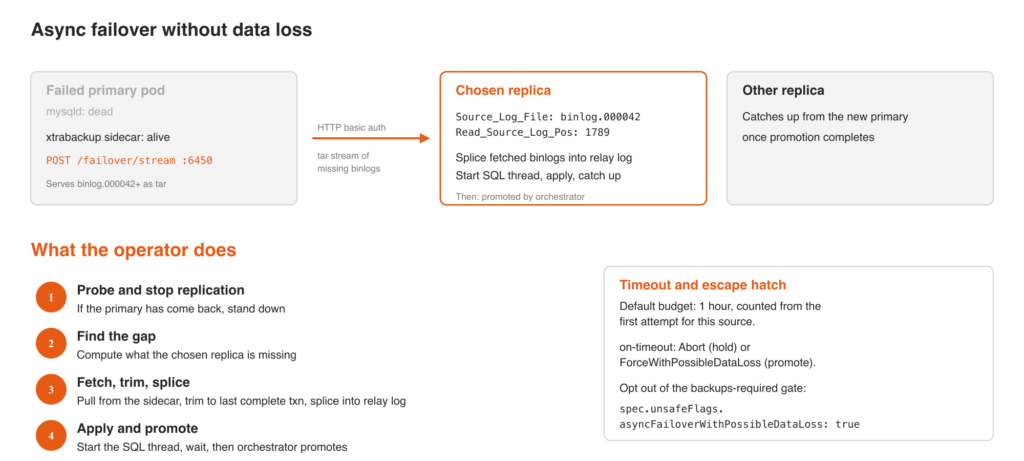
Async MySQL replication, by definition, acknowledges a transaction to the client before any replica has it. If the primary dies with transactions in its binary log that no replica has read yet, those transactions are gone, even with a well-configured HA controller.
The operator extends the xtrabackup sidecar on every MySQL pod with a POST /failover/stream endpoint on port 6450 that serves binary logs as a tar stream. When the primary fails, the failover tool runs on the chosen replica.
Source_Log_File and Read_Source_Log_Pos to find the gap.Only then does the orchestrator promote the chosen replica.
The failover has a budget. By default, the failover tool waits up to one hour for the source pod to become reachable and apply the missing transactions. When the budget expires, the on-timeout policy decides what happens: Abort holds the cluster, or ForceWithPossibleDataLoss promotes anyway. The budget is counted from the first attempt, not per retry.
Because the mechanism requires the failed primary’s pod to be reachable (its mysqld can be down, but its sidecar must answer), the CRD now validates that backups are enabled on async clusters. To opt out of this gate and restore the pre-1.3.0 behavior, set spec.unsafeFlags.asyncFailoverWithPossibleDataLoss: true.
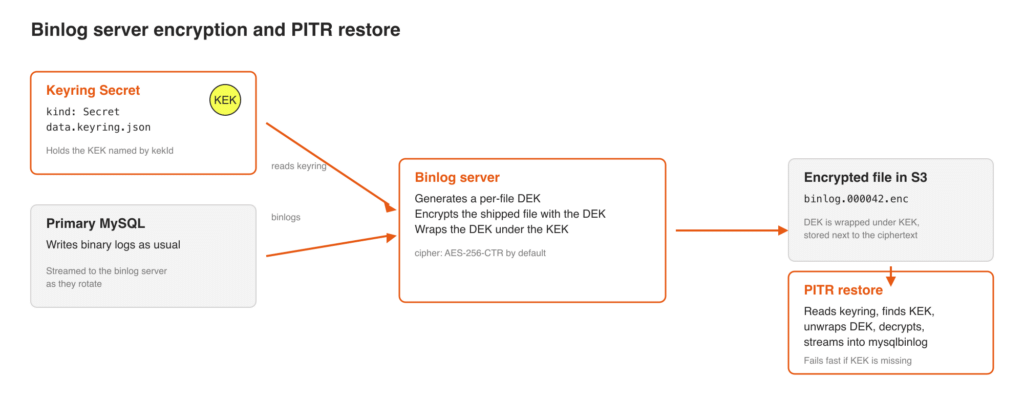
The operator’s binlog server ships binary logs to object storage for point-in-time recovery. In 1.3.0 those shipped files can be encrypted at rest, with the key material held in a Kubernetes Secret instead of being carried on each MySQL pod.
The binlog server uses envelope encryption. A per-file data encryption key (DEK) encrypts each binlog file. That DEK is itself wrapped under a key encryption key (KEK) that the operator reads from a keyring Secret. The CR surfaces three fields for this:
spec.backup.pitr.binlogServer.storage.encryption.cipher picks the symmetric cipher (AES-256-CTR by default).spec.backup.pitr.binlogServer.storage.encryption.kekId names the KEK entry inside the keyring.spec.backup.pitr.binlogServer.keyringSecret points at the Kubernetes Secret that holds the keyring file (default key keyring.json).On the restore side, the PITR tool reads the keyring, finds the KEK named in the file’s metadata, unwraps the file key, and streams the decrypted events through mysqlbinlog into the restored MySQL. If the keyring is missing or the named KEK is not in it, the restore fails fast with an explicit error rather than producing partially restored data.
Enable PITR with an encrypted binlog server. The relevant block in the CR is spec.backup.pitr.binlogServer, which carries its own encryption sub-block and a reference to the keyring secret:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 |
apiVersion: ps.percona.com/v1 kind: PerconaServerMySQL metadata: name: cluster1 spec: backup: enabled: true pitr: enabled: true binlogServer: storage: encryption: cipher: AES-256-CTR kekId: alpha s3: bucket: S3-BACKUP-BUCKET-NAME-HERE credentialsSecret: ps-cluster1-s3-credentials endpointUrl: https://s3.amazonaws.com region: us-west-2 keyringSecret: key: keyring.json name: ps-cluster1-binlog-server-keyring |
The encryption.cipher and encryption.kekId fields are what tell the binlog server to encrypt shipped binary logs at rest. The keyringSecret provides the master key material.
The release notes have the full list with ticket IDs. The highlights:
spec.users list, each with name, optional passwordSecretRef, dbs, hosts, grants, and withGrantOption.PSO_LEADER_ELECTION_* environment variables on the operator Deployment.Percona Operator for MySQL 1.3.0 tightens the parts of a MySQL platform that reviews and on-call rotations care about most: autoconfig gives each pod the configuration its CPU and memory actually warrant, zero data loss failover salvages the transactions stranded on a failed primary before promoting a replica, and encrypted binlog shipping lets point-in-time recovery stay on, under keys you control, for clusters where encryption at rest is a hard requirement. Application users in the CR, custom CAs for private S3 endpoints, and in-place TLS rotation move more day-two work out of runbooks and into the spec. If there is a workflow you still script around the operator, tell us on the forum, since that is where releases like this one come from.
Resources
RELATED POSTS