We loaded 990,000 OpenAI embeddings of 1,536 dimensions into six databases that index vectors themselves, built an HNSW index in each, and measured five things: time to a queryable index, storage and memory, recall against throughput, throughput under concurrent clients, and what happens when 10% of the corpus is rewritten. Same host, same container shape, same source pins, same query set.
The build numbers spread wider than we expected. Time to a queryable index ran from 1.9 minutes to 6.7 hours for the same million vectors. Index size ran from 3.9 GiB to 15.1 GiB, and the engine with the smallest index took the longest to build it. At recall 0.99 the field closes up: four of the six are within a factor of two of each other. Under 32 clients it opens again. pgvector returns 21.7× its single-client throughput. The three InnoDB-based engines return about 1×.
This is one run on one machine. Two numbers in the concurrency table have since been withdrawn by the harness that produced them, and the reason is below. Framework, configuration and raw records: github.com/Percona-Lab/vector-bench.
<
| Host | Intel Xeon Gold 6230 @ 2.10 GHz, 80 logical CPUs, AVX-512, 187.5 GB RAM |
|---|---|
| Server container | CPUs 0–63, 120.8 GB memory limit, 13 GB /dev/shm |
| Harness container | CPUs 64–79, 8 GB memory limit |
| Corpus | dbpedia-openai-1000k-angular, 990,000 × 1,536 float32, cosine |
| Index | HNSW, M = 16 everywhere, k = 10 |
| Query effort | ann pass sweeps ef_search 10–800, ops pass pins ef_search 100 |
| Concurrency | 1, 2, 4, 8, 16, 32 clients, 60 s per point, 3 repeats |
| Filters | 500 queries per point at 10% and 1% selectivity |
| Churn | 10% of the corpus deleted and re-inserted |
| Build | RelWithDebInfo, -march=x86-64-v3 for all four built from source |
The database runs in one container and the harness in another, on a private network. One container would charge the several hundred megabytes of NumPy holding the query set to the server’s cgroup and ruin the memory numbers. The harness never configures a server. The orchestrator does, so every engine gets the same treatment, and that treatment is written into the run manifest beside the results.
All six got the same budget: a 42.3 GB InnoDB buffer pool, 12.1 GB of maintenance_work_mem for pgvector’s build, 8 I/O threads and 8 build threads. The two engines with a graph cache got 30.2 GB of it. Both default to 16 MiB, and leaving that in place would judge a vendor on a value it plainly intends you to change. The orchestrator clamped I/O and build threads down from 64, because more than a handful contend rather than help and a large value stalled writes into a populated index outright. It raised /dev/shm from 8 GB to 13 GB so pgvector’s parallel build could hold a segment the size of maintenance_work_mem. Both adjustments are in the manifest.
Recall is ann-benchmarks’ distance-threshold definition, so these numbers stay comparable with published ANN results. Ground truth for filtered queries is recomputed by brute force over the rows that satisfy each predicate. A WHERE clause changes the correct answer set, and scoring a filtered query against unfiltered neighbours scores every engine against the wrong targets.
| Engine | Version | Index | Source |
|---|---|---|---|
| MariaDB 11.8 | 11.8.8 | MHNSW | built from tag |
| MariaDB 12.3 | 12.3.2 | MHNSW | built from tag |
| AliSQL | 8.0.44-2 | VIDX | built from tag |
| PostgreSQL + pgvector | pgvector 0.8.6 | HNSW | built from tag |
| Valkey + valkey-search | 9.1.1 | HNSW | Percona packages |
| Percona Search for MongoDB | 1.70.3-1 on PSMDB 8.3.8-2 | HNSW | Percona packages |
Percona Search for MongoDB is a Technical Preview and its documentation says not for production. Its numbers use the scalar-quantized index, which MongoDB recommends above a 3 GB vector index.
| Engine | Load | Index build | To queryable | Rows/s | Index | Table | Peak RSS |
|---|---|---|---|---|---|---|---|
| Percona Search | 14 s | 100 s | 1.9 min | 69,018 | 15.1 GiB | 5.8 GiB | 48.8 GiB |
| Valkey | 33 s | 226 s | 4.3 min | 30,170 | 11.3 GiB | 6.9 GiB | 14.3 GiB |
| PostgreSQL | 26.9 min | 14.0 min | 40.9 min | 613 | 7.6 GiB | 7.6 GiB | 43.5 GiB |
| MariaDB 11.8 | 3.6 h | in the load | 3.6 h | 75.9 | 3.9 GiB | 14.3 GiB | 28.6 GiB |
| MariaDB 12.3 | 5.4 h | in the load | 5.4 h | 50.7 | 3.9 GiB | 14.4 GiB | 27.0 GiB |
| AliSQL | 6.7 h | in the load | 6.7 h | 41.0 | 3.9 GiB | 10.5 GiB | 21.9 GiB |
MHNSW and VIDX update the graph on every INSERT, so their load is the index build and there is nothing separate to time. That puts them at 41 to 76 rows a second against pgvector’s 613 and Valkey’s 30,170. pgvector’s 40.9 minutes is 26.9 minutes of COPY plus 14.0 minutes of parallel build across 8 workers.
They get the smallest index for it. 3.9 GiB, where the raw float32 vectors alone are 5.7 GiB. It is the only measurement in this run where MariaDB leads, and it matters when index-resident-per-node is the binding constraint. The table is a different story: MariaDB stores 14.3 GiB for those same vectors, Percona Search 5.8 GiB.
Build time is a re-indexing window. Changing embedding model is an afternoon on pgvector and a weekend on AliSQL.
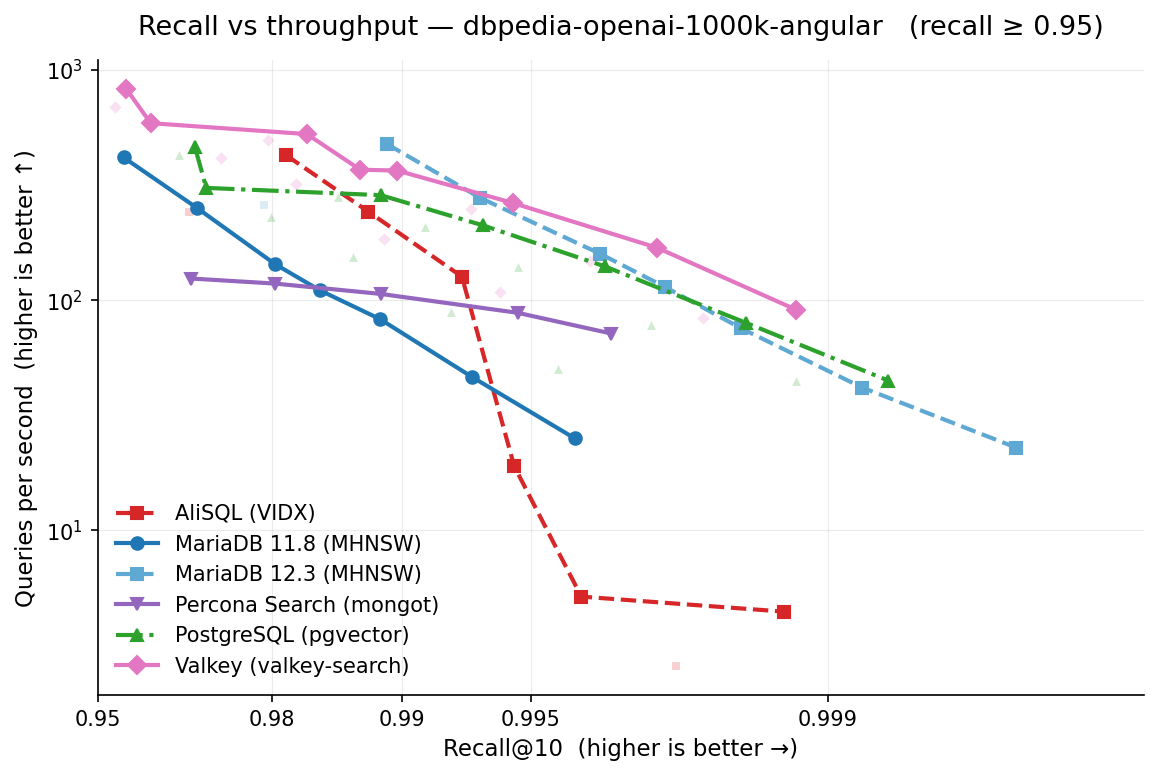
| Engine | recall ≥ 0.90 | ≥ 0.95 | ≥ 0.99 |
|---|---|---|---|
| Valkey | 1,191 | 825 | 264 |
| PostgreSQL | 679 | 462 | 210 |
| MariaDB 12.3 | 475 | 475 | 277 |
| AliSQL | 424 | 424 | 126 |
| MariaDB 11.8 | 415 | 415 | 46 |
| Percona Search | 138 | 124 | 88 |
Best throughput whose measured recall clears each floor. MariaDB and AliSQL repeat a number across two columns because their fastest configuration already returns recall 0.956 to 0.989. It wins both floors. That is not a missing measurement.
MariaDB 12.3 is the fastest engine in the run at recall 0.99, at 277 QPS. It gives six times the throughput of 11.8 at that floor for 50% more build time. That is a better graph rather than faster search, and it is the case for upgrading if accuracy above 0.99 is the target.
Raising the floor from 0.90 to 0.95 costs pgvector and Valkey a third of their throughput. It costs MariaDB and AliSQL nothing, because their fastest setting is already above both floors. Neither MHNSW nor VIDX exposes a knob that trades accuracy for speed at a fixed graph degree, so there is no cheaper operating point to move to. pgvector and Valkey expose ef_construction as well as a query-time knob.
One AliSQL point is unexplained. At M = 16, throughput rises from 2.6 to 4.4 QPS between ef_search 400 and 800. More search effort cannot be faster on the same index. AliSQL also has a latency cliff: p50 is 6.6 ms at ef_search 80, 50.8 ms at 120 and 384 ms beyond, reproduced across three runs, two corpus sizes and both graph degrees with no competing load on the host.
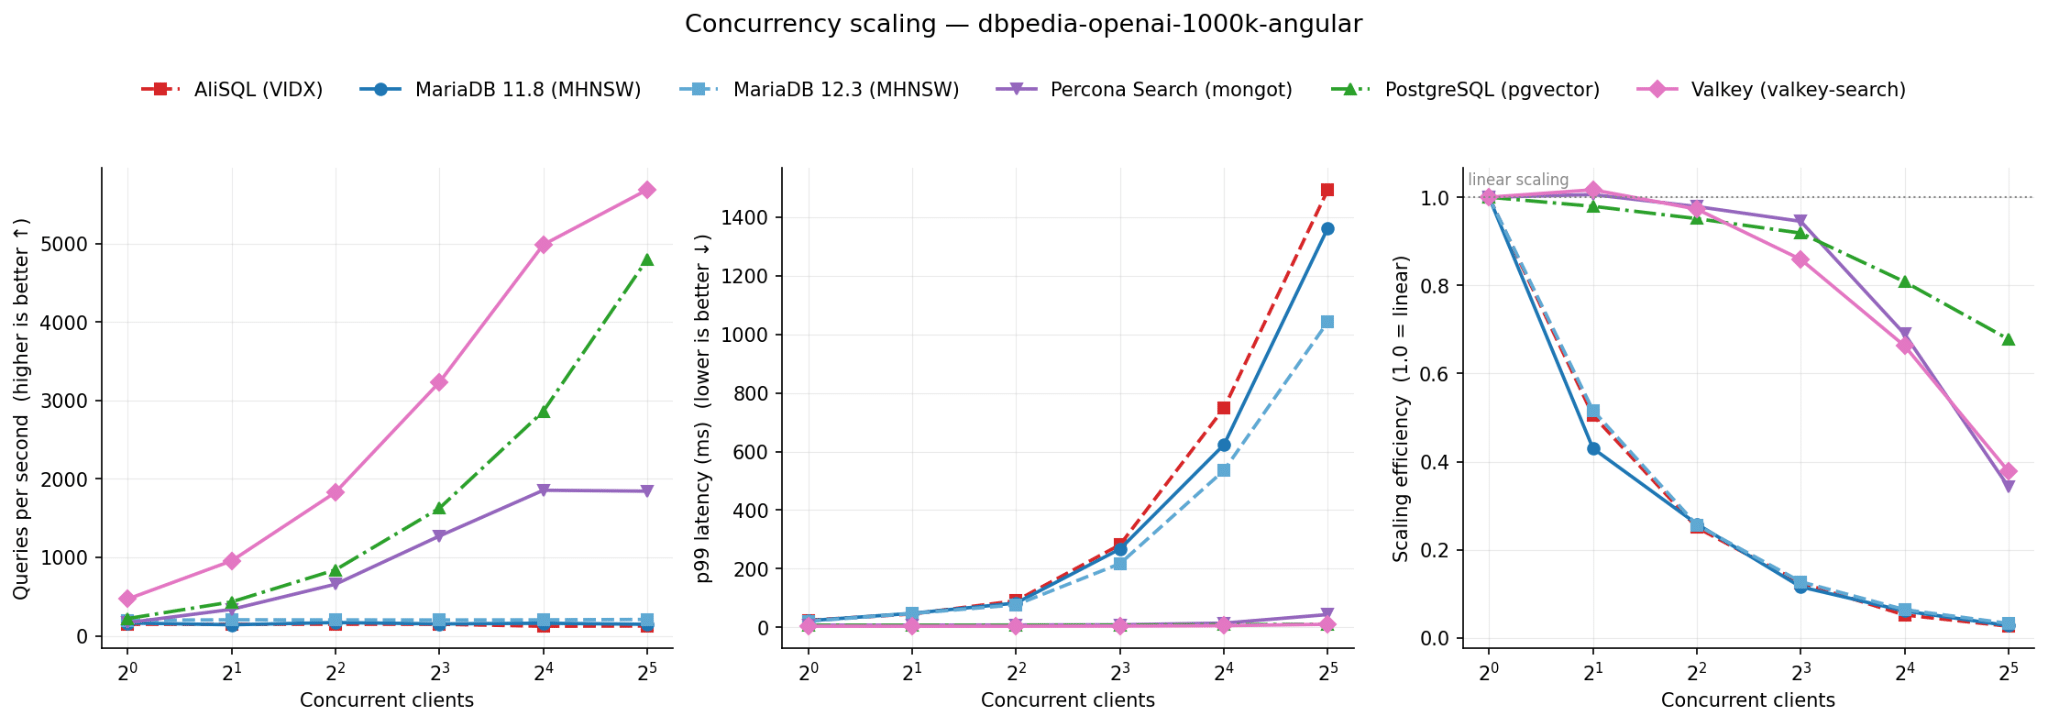
| Engine | 1 | 2 | 4 | 8 | 16 | 32 | p99 @32 | In service @32 |
|---|---|---|---|---|---|---|---|---|
| Valkey | 470 | 956 | 1,829 | 3,230 | 4,983 | 5,683 | 10.2 ms | 30.7 of 32 |
| PostgreSQL | 221 | 433 | 842 | 1,626 | 2,861 | 4,798 | 10.8 ms | 31.9 of 32 |
| Percona Search | 168 | 339 | 659 | 1,272 | 1,856 | 1,844 | 43.5 ms | 28.8 of 32 |
| AliSQL | 148 | 150 | 149 | 149 | 124 | 127 | 1,494 ms | 16.9 of 32 |
| MariaDB 11.8 | 165 | 142 | 171 | 153 | 162 | 148 | 1,364 ms | 14.4 of 32 |
| MariaDB 12.3 | 199 | 206 | 204 | 204 | 205 | 210 | 1,043 ms | 7.1 of 32 |
“In service” is throughput times median latency. By Little’s law that is the average number of queries inside the engine during the window. For the top three it tracks the client count, so the x-axis means what it says. For the two MariaDB builds it does not. At nominally 32 clients, 14.4 and 7.1 queries were in service.
Why are two cells marked? Our harness runs its concurrent clients as threads in one Python interpreter, each with its own connection. MariaDB Connector/C holds the interpreter lock across its socket wait, so some of those clients were waiting on the lock rather than on the database. A later smoke run made it obvious: at 4 clients on a small corpus, MariaDB returned 2,927 QPS at a 0.325 ms median, which is one query in flight.
The harness now computes “in service” for every window and refuses to divide throughput by the client count when it falls below half. On this run that refuses MariaDB 11.8 at 16 and 32 clients, MariaDB 12.3 at 2, 16 and 32, and AliSQL at 2. Six points of thirty-six. It refuses nothing from pgvector, Valkey or Percona Search. It also does not refuse a saturated server: a real queue raises the whole latency distribution including the median, so “in service” stays at the client count while throughput flattens.
The finding survives the withdrawal. Throughput did not rise and median latency rose twentyfold. MariaDB 11.8 returned 165 QPS at one client and 148 at thirty-two, p50 going 4.6 ms to 97 ms. AliSQL went 5.1 ms to 133 ms for the same flat throughput. Offering an engine more work and getting the same throughput at twenty times the latency is a queue, and that queue was on the server side. A client still waiting for the interpreter lock has not issued its query and adds nothing to these percentiles. What we cannot claim is that these three were measured at 32 concurrent queries. They were measured at 7 to 17.
The three flat engines are the three on InnoDB. They are also the three driven through MariaDB Connector/C, where the others use psycopg3, PyMongo and a Valkey client. Two variables, three engines, one pattern. The grouping cannot separate them and nothing here has been profiled. MHNSW and VIDX are separate codebases from different teams, which is what makes the storage engine the interesting half.
The same arithmetic shows one more thing. At a single client, pgvector, Valkey and Percona Search spent 99 to 101% of the window inside the query call. MariaDB 11.8, MariaDB 12.3 and AliSQL spent 74 to 75%. About 1.5 ms per query on that path is our harness, not the server, so their single-client latencies read worse than the engine is. Throughput is unaffected.
Every engine here answers “nearest neighbours of this vector where a scalar predicate holds”. They do it three different ways, and the ways diverge as the predicate tightens.
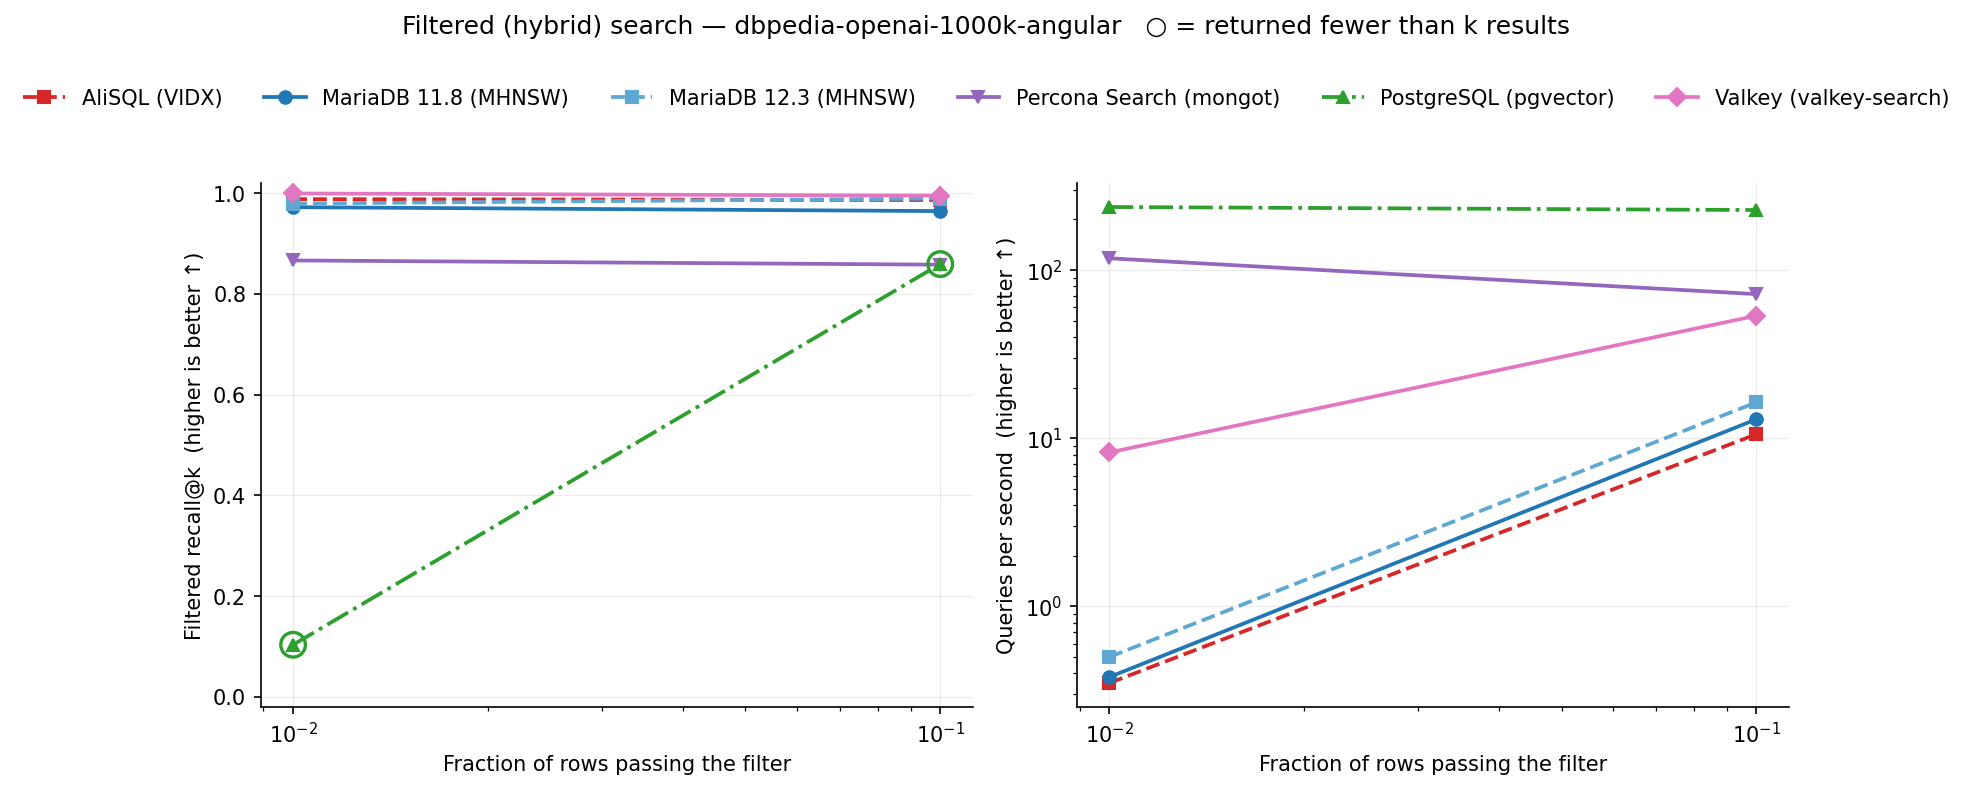
| Engine | Strategy | 10% selective | 1% selective | |||
|---|---|---|---|---|---|---|
| Recall | QPS | p99 | Recall | QPS | ||
| Valkey | planned per query | 0.9952 | 53.5 | 36 ms | 0.9996 | 8.2 |
| MariaDB 12.3 | post-filter, keeps going | 0.9896 | 16.4 | 322 ms | 0.9796 | 0.5 |
| AliSQL | post-filter, keeps going | 0.9866 | 10.6 | 447 ms | 0.9884 | 0.3 |
| MariaDB 11.8 | post-filter, keeps going | 0.9646 | 13.0 | 366 ms | 0.9724 | 0.4 |
| Percona Search | pre-filter | 0.8582 | 71.9 | 25 ms | 0.8666 | 117.5 |
| PostgreSQL | post-filter, stops | 0.8594 | 227.5 | 6.4 ms | 0.1034 | 237.1 |
Recall is scored against ground truth recomputed over the qualifying rows only. pgvector’s two recall figures are marked because its queries returned fewer than k rows: 224 of 500 at 10% selectivity, all 500 at 1%.
pgvector post-filters and then stops. It walks the graph, collects ef_search candidates, and drops the ones that fail the predicate. At 1% selectivity nearly all of them fail, so the query returns one or two rows where ten were asked for. No error, no warning, full speed. Recall 0.1034 is a short answer rather than a bad one. Iterative scan exists in pgvector 0.8 for this case and was not measured here, so this is the cost of the default. The default is what an application gets if nobody knows to change it.
MariaDB and AliSQL post-filter too, but keep searching until enough rows survive. Recall holds above 0.97 and throughput goes under one query a second, with a p99 of ten to thirteen seconds.
Percona Search pre-filters, which is why it is the only engine that gets faster as the predicate tightens: 71.9 QPS at 10% selectivity, 117.5 at 1%. Its recall is the lowest of the five that answer completely, 0.858 to 0.867, and that is the scalar quantization rather than the filter. Unquantized it reaches 0.997 on this corpus, at the same index size. Valkey plans per query and is the only engine that is both accurate and usable at 1%.
Delete 99,000 rows, re-insert the same 99,000, measure the index again.
| Engine | QPS before | QPS after | Change | Recall after | Re-insert rate |
|---|---|---|---|---|---|
| PostgreSQL | 244 | 245 | +0.4% | 0.9816 | 128 rows/s |
| Valkey | 479 | 460 | −4.0% | 0.9742 | 137 rows/s |
| Percona Search | 186 | 113 | −39.2% | 0.8416 | 20,223 rows/s |
| MariaDB 12.3 | 156 | — | — | — | 28.1 rows/s |
| MariaDB 11.8 | 152 | — | — | — | 22.8 rows/s |
| AliSQL | 138 | — | — | — | 16.1 rows/s |
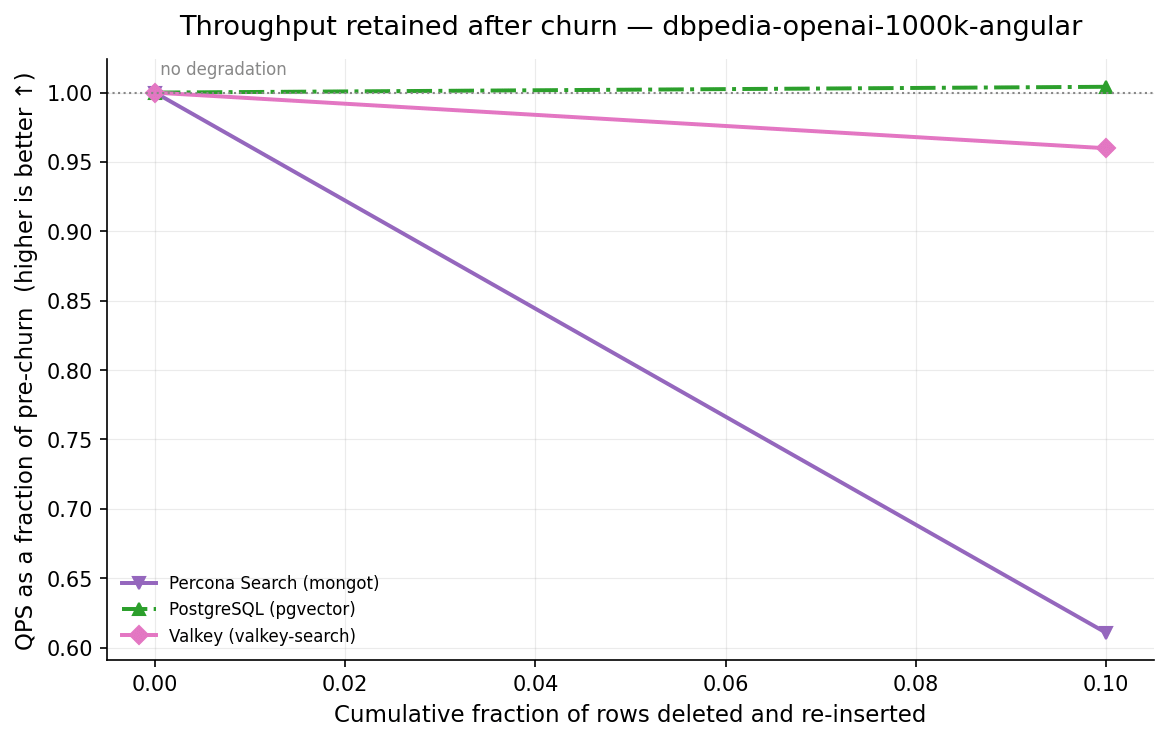
The three dashes are our bug, not an engine result. Each re-insert gets a wall-clock budget so a stalled write releases the machine instead of holding the run overnight. We set it to thirty minutes, sized against a Valkey defect where pipelined writes into an indexed prefix never returned. Thirty minutes is far too short for an engine doing the work slowly and correctly. MariaDB 12.3 got 51,480 rows of 99,000 in, MariaDB 11.8 got 41,580, AliSQL got 29,700, and the post-churn measurement never ran. The budget is two hours now. Recovering those three cells costs about 24 hours, most of it reloading the corpus.
The partial run still answers the question we wanted. Re-inserting into a populated index runs at 16 to 28 rows a second, against 41 to 76 for the initial load. Writing into an established graph costs two to three times what building it does, on all three engines. These re-inserts ran with no reader threads in the interpreter, which the records confirm, so the concurrency problem above does not touch them.
Percona Search loses 39%, the largest drop in the table, while recall goes 0.8432 to 0.8416. The index is not degrading, the throughput is. pgvector is flat because its repair path ran: VACUUM (ANALYZE) after the re-insert, the only maintenance hook any engine here exposes for this.
The run manifest holds the host, the resolved budgets, the image IDs and the source commit of every engine, and the report generator refuses a run directory without one.
Choosing on this evidence: pgvector for concurrent traffic, where 4,798 QPS at a 10.8 ms p99 is an order of magnitude clear of the MySQL family, provided someone turns on iterative scan before shipping a filtered query. Valkey if the working set fits in memory and you need filters that are both accurate and fast; test its write path into an indexed prefix first. MariaDB 12.3 if the index has to be small and accurate and the traffic is a handful of concurrent clients. It is the fastest engine here at recall 0.99 and its index is a quarter the size of Percona Search’s. Percona Search if a tight predicate is the common case, since it is the only engine that speeds up as the filter narrows, and if a Technical Preview is acceptable. MariaDB 11.8 does nothing 12.3 does not do better. AliSQL builds slowest and has a latency cliff above ef_search 80.
Where it stops: one corpus at one dimensionality, one graph degree for half the field, one machine, one run, no profiling of the concurrency ceiling, and no second observation of anything. The numbers most likely to move under a re-run are the three missing churn cells and the six refused concurrency points. The least likely are build time, index size and recall, which agreed across earlier runs at two corpus sizes.
|
1 2 3 4 5 6 7 |
<code>git clone https://github.com/Percona-Lab/vector-bench cd vector-bench ./run-benchmark.sh build --engines all ./scripts/generate-dataset.sh dbpedia-openai-1000k-angular ./run-benchmark.sh run --profile tuned-complete --run-id <id> ./run-benchmark.sh report --run-dir <id> \ --datasets dbpedia-openai-1000k-angular</code> |
All runs can take about 40 hours, nearly all of it the incremental builds. Smaller profiles exist for checking the pipeline before committing a machine for two days: --profile dev is about a minute per engine on a synthetic corpus, --profile smoke about 45 minutes per pass and it exercises every chart. The run directory keeps the records, the manifest, per-phase logs and memory timeseries, so any number here traces back to the process that produced it. Issues and corrections are welcome.
Run full-20260825, profile tuned-complete, tuned resource pass, dbpedia-openai-1000k-angular, 990,000 × 1,536, M = 16, k = 10. Versions: MariaDB 11.8.8, MariaDB 12.3.2, AliSQL 8.0.44-2, pgvector 0.8.6, Valkey 9.1.1 with valkey-search, Percona Search for MongoDB 1.70.3-1 on PSMDB 8.3.8-2. One run, all of it. Missing measurements are marked missing, not estimated. Charts are the ones the framework generates.
Resources
RELATED POSTS